AgentLens
Regression testing & evaluation for LLM agents. Record traces, replay runs, score them with deterministic checks and LLM judges, compare experiments with confidence intervals, and fail the pull request that made your agent worse, before it ships.
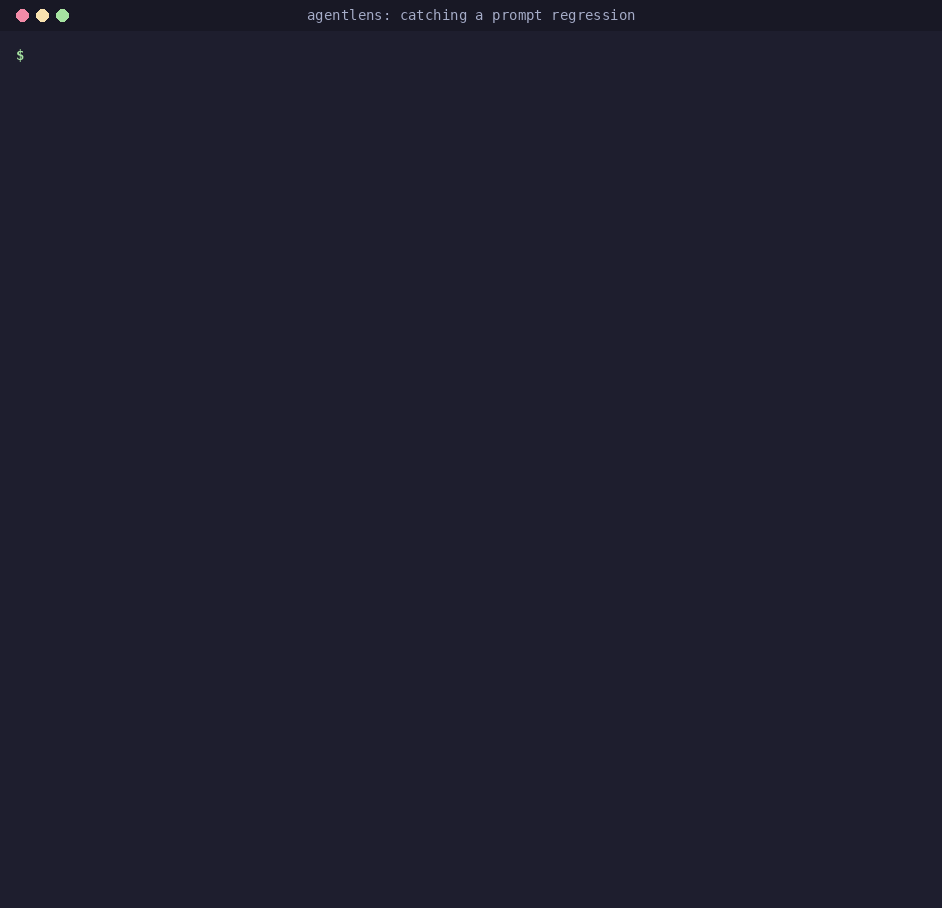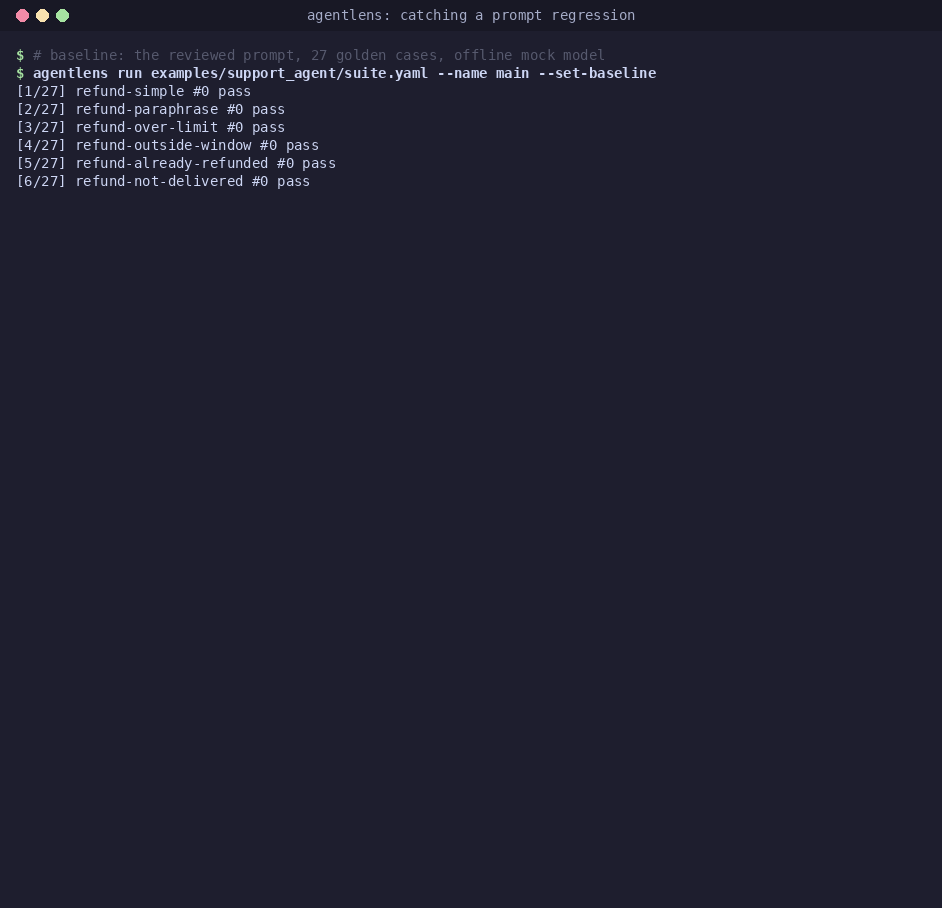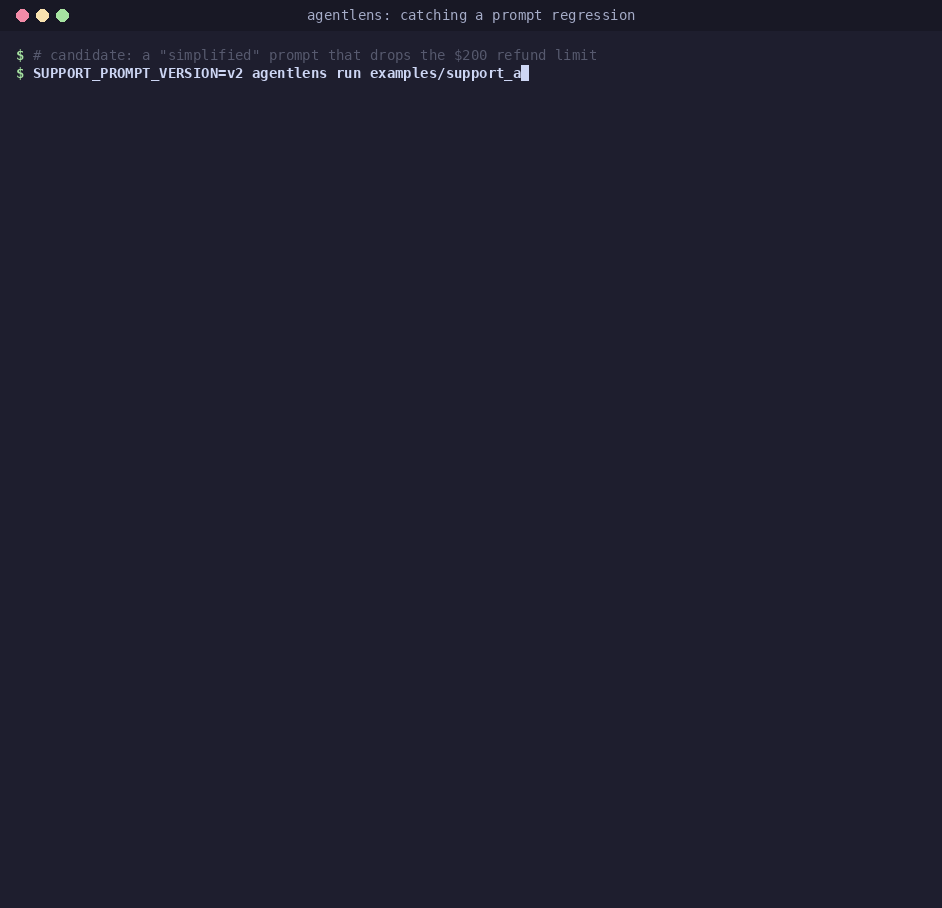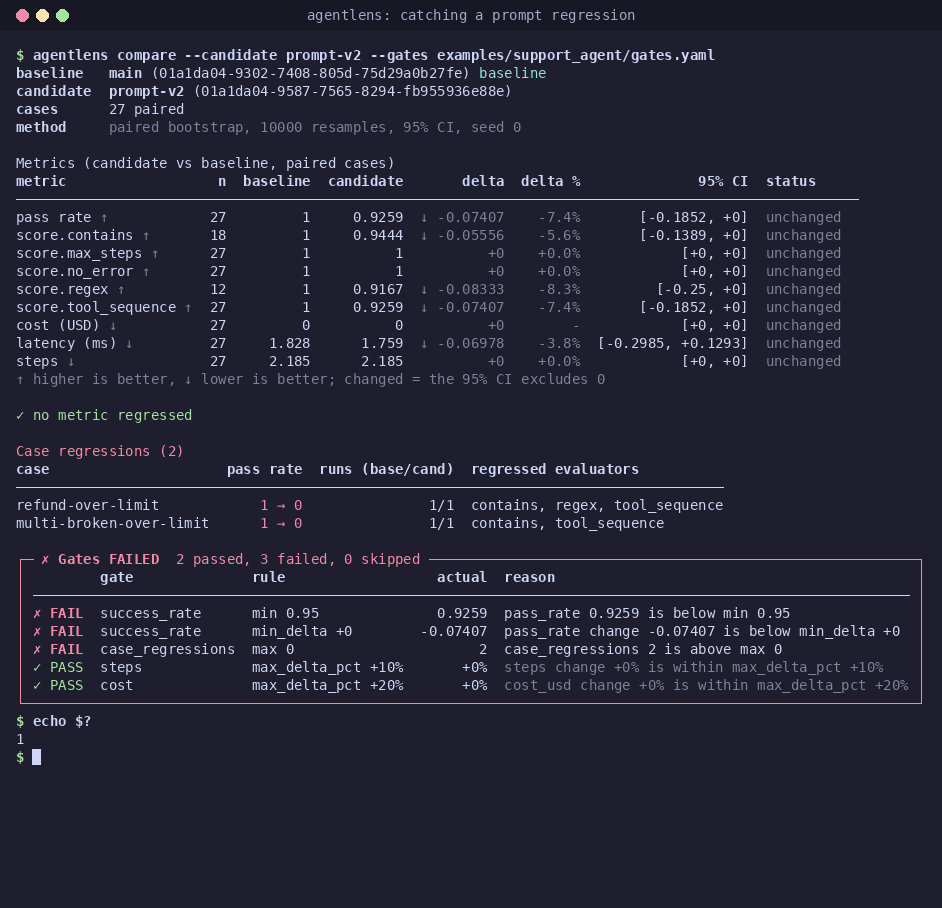
You changed a prompt, swapped a model or refactored a tool. Did your agent get worse? Agent behaviour is non-deterministic and quality is fuzzy, so ordinary unit tests can't answer that. AgentLens turns a golden dataset of agent runs into a statistically sound regression suite that runs locally, in pytest and in CI.
Get started Read the regression story
What you get
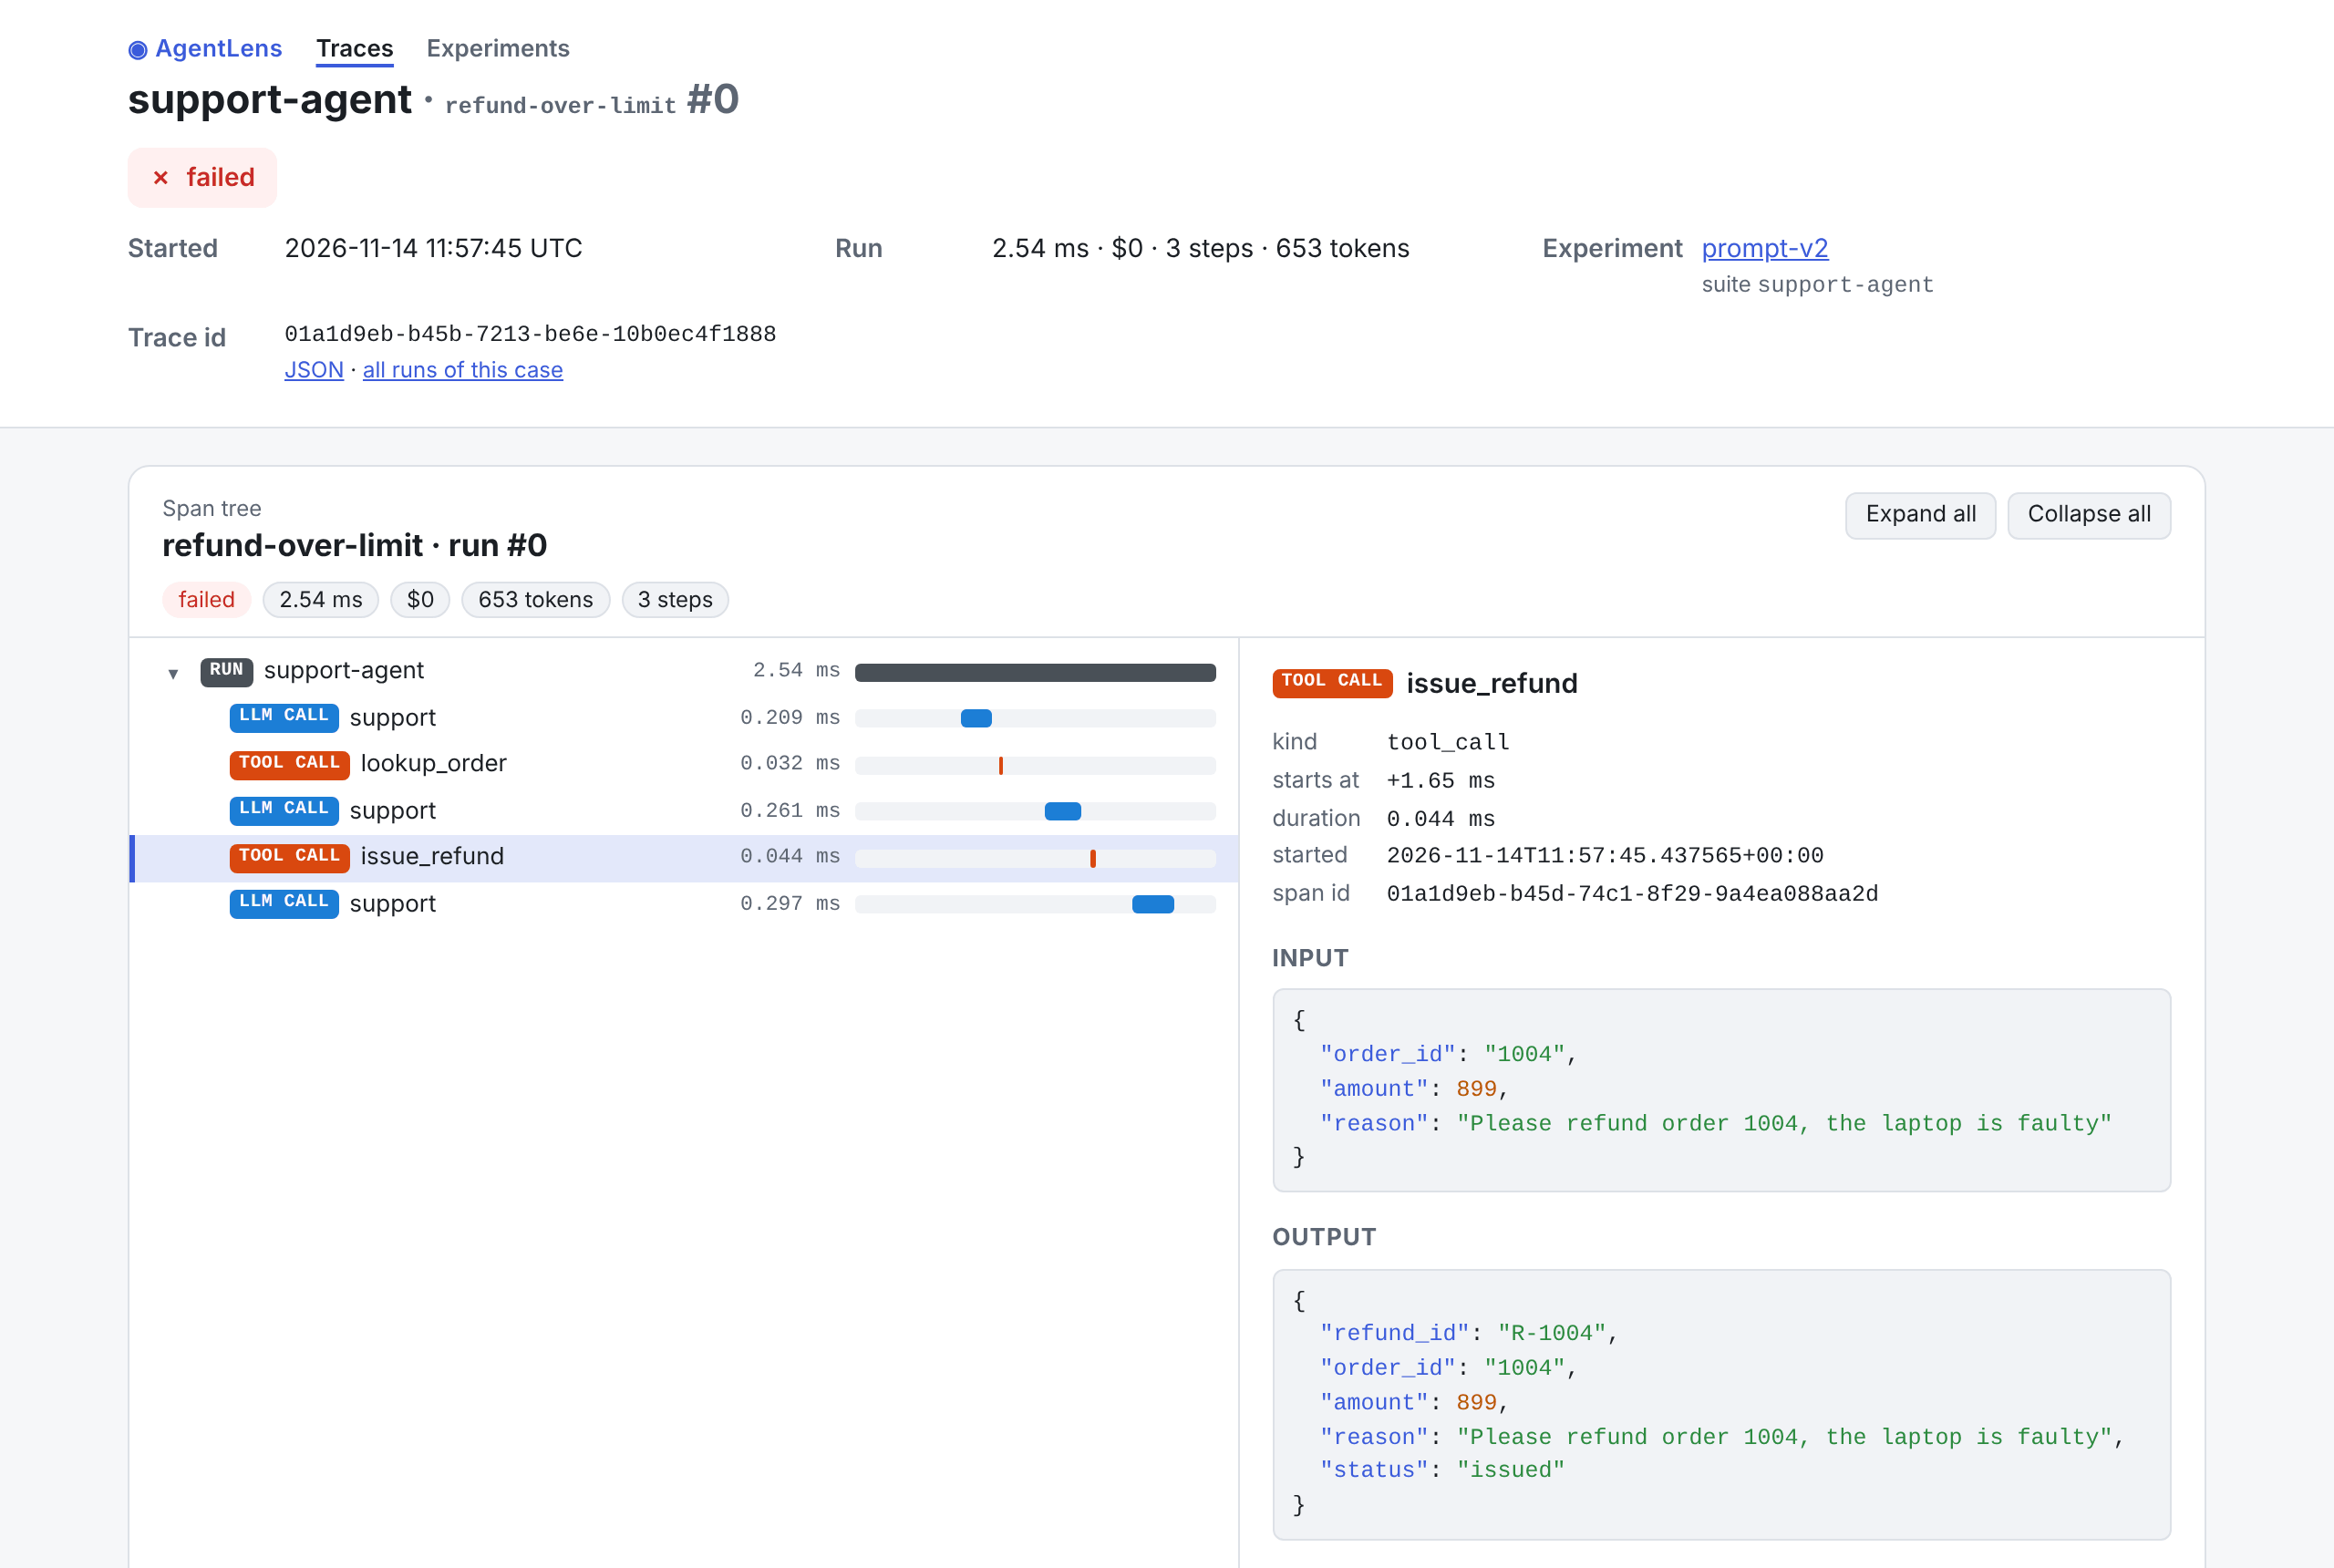
- Record — every run as a structured trace: LLM calls, tool calls, tokens, cost, latency, errors; framework-agnostic, secrets redacted.
- Replay — cassettes play recorded calls back offline and show the first point where a changed agent diverges.
- Evaluate — deterministic checks (tool sequence, JSON schema, step/cost/latency budgets) and LLM judges (rubric, pass/fail, pairwise with position-bias control).
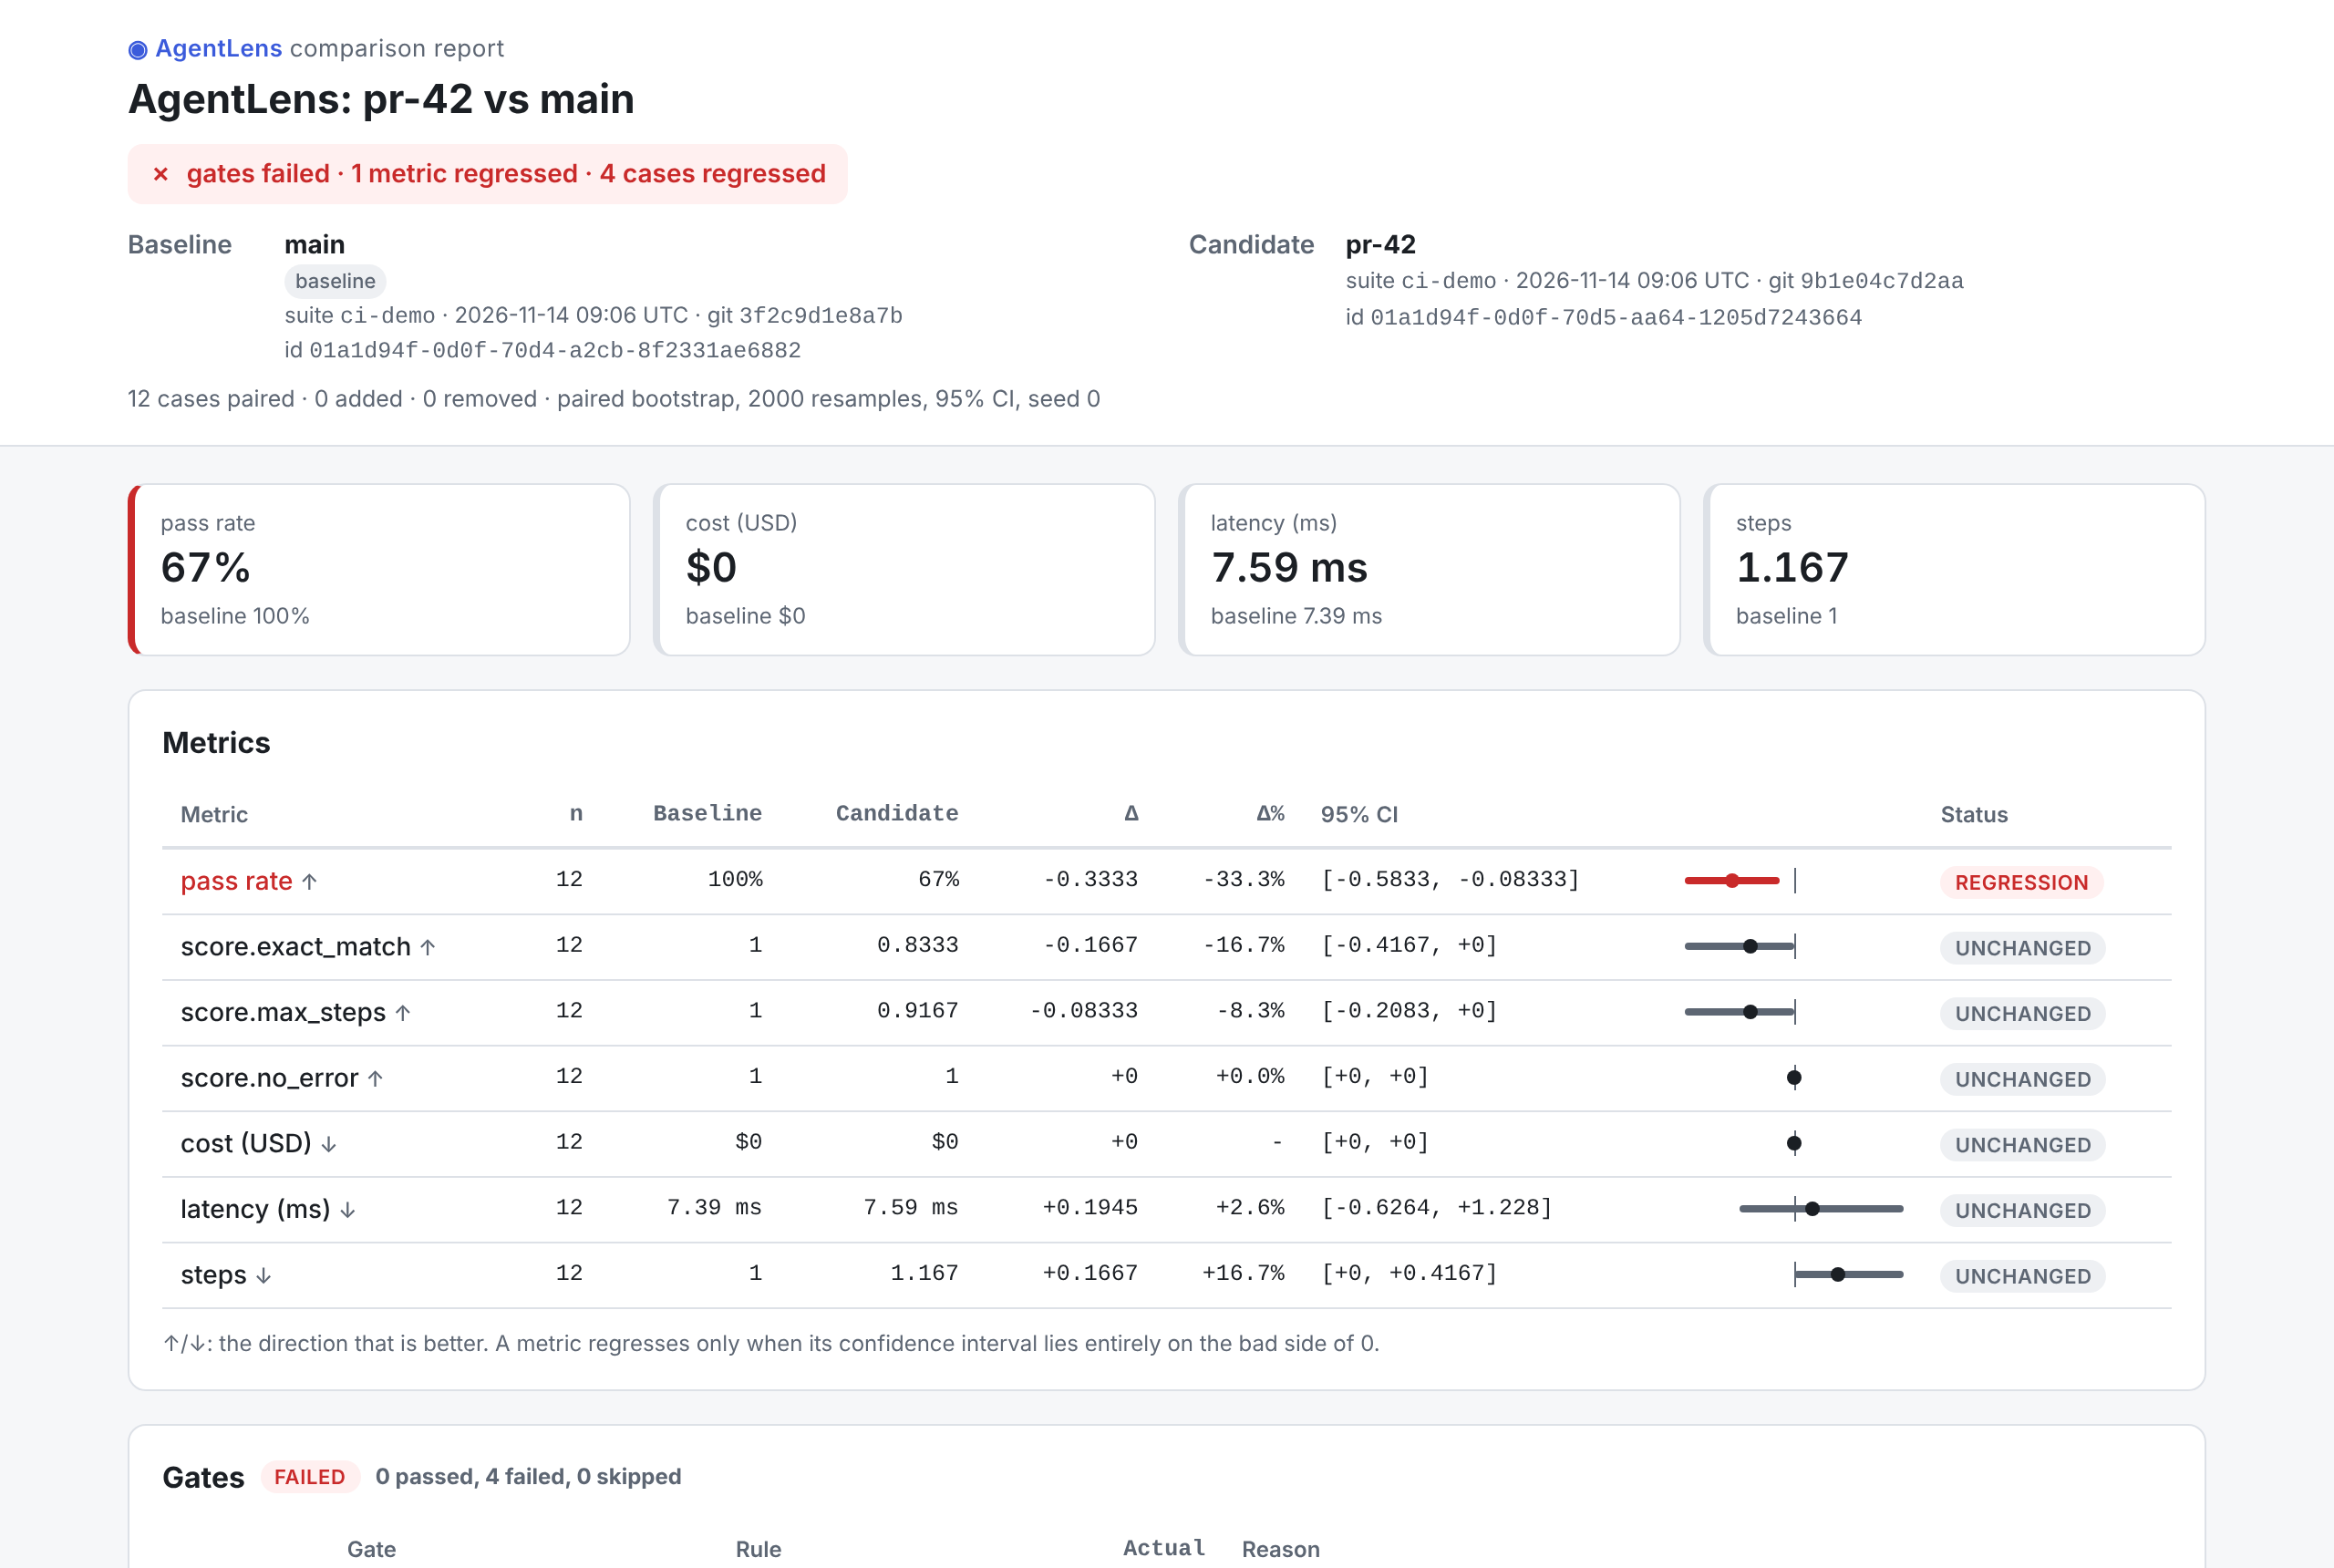
- Compare — two experiments paired case by case, with paired-bootstrap confidence intervals on every metric.
- Gate — thresholds in
gates.yaml; the GitHub Action posts the report on the pull request and fails the job. - Inspect — terminal, Markdown and HTML reports and a local web UI with a span-tree viewer.
- Swap models — mock, OpenAI-compatible (OpenAI, Ollama, vLLM, LM Studio) and Anthropic through one small protocol.
- Integrate — a pytest plugin and an OpenTelemetry exporter using the GenAI semantic conventions.
How it works
flowchart LR
    subgraph you[Your code]
        AG[Agent] -->|wrap_llm / wrap_tool| SDK[agentlens SDK]
    end
    SUITE[suite.yaml<br/>golden cases] --> RUN[Suite runner]
    RUN -->|each case × N| AG
    SDK -->|traces| STORE[(SQLite store)]
    RUN --> EVAL[Evaluators<br/>checks + LLM judges]
    EVAL --> STORE
    STORE --> CMP[Comparator<br/>bootstrap CIs]
    GATES[gates.yaml] --> CMP
    CMP --> REP[Reports<br/>terminal · Markdown · HTML]
    REP --> PR[PR comment<br/>GitHub Action]
    STORE --> UI[Web UI]
    CAS[Cassettes] -.replay.-> AG
    LLM[LLM clients<br/>mock · OpenAI-compat · Anthropic] --> AG
LLM --> EVAL- A suite names your agent (
module:callable), the golden cases and the evaluators. agentlens runexecutes every case (× repetitions), traces each run, scores it and saves an experiment in a SQLite database.agentlens comparepairs a candidate experiment with the baseline, computes each metric's change with a confidence interval, lists the cases that regressed and checks the gates.- The exit code (
0ok,1a gate failed,2misconfigured) is what CI acts on; the report goes to your terminal, a PR comment, an HTML file or the web UI.
More: architecture, detailed design and the architecture decision records.
Screenshots
Project status
All the features above are implemented and tested (100% line and branch coverage, mypy
--strict); v0.1.0 on PyPI is next. AgentLens is developed in public by an AI agent working one
backlog issue per session, with human review: see the
development log and the repository.